
本文首发极市平台公众号,转载请获得授权并标明出处。
ECCV 2022 论文分方向整理目前在极市社区持续更新中,已累计更新了54篇,项目地址:https://github.com/extreme-assistant/ECCV2022-Paper-Code-Interpretation
以下是本周更新的 ECCV 2022 论文,包含检测,分割,图像处理,视频理解,神经网络结构设计,无监督学习,迁移学习等方向。
论文合集打包下载地址:https://www.cvmart.net/community/detail/6592
– 检测 – 分割 – 图像处理 – 视频处理 – 图像、视频检索与理解 – 估计- 目标跟踪 – 文本检测与识别 – GAN/生成式/对抗式 – 神经网络结构设计 – 数据处理 – 模型训练/泛化 – 模型压缩 – 模型评估 – 半监督学习/自监督学习 – 多模态/跨模态学习 – 小样本学习 – 强化学习
检测
2D目标检测
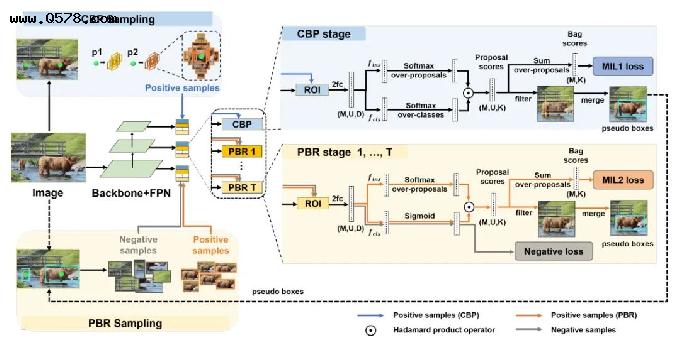
[1] Point-to-Box Network for Accurate Object Detection via Single Point Supervision (通过单点监督实现精确目标检测的点对盒网络)paper:https://arxiv.org/abs/2207.06827code:https://github.com/ucas-vg/p2bnet
[2] You Should Look at All Objects (您应该查看所有物体)paper:https://arxiv.org/abs/2207.07889code:https://github.com/charlespikachu/yslao
[3] Adversarially-Aware Robust Object Detector (对抗性感知鲁棒目标检测器)paper:https://arxiv.org/abs/2207.06202code:https://github.com/7eu7d7/robustdet
3D目标检测
[1] Rethinking IoU-based Optimization for Single-stage 3D Object Detection (重新思考基于 IoU 的单阶段 3D 对象检测优化)paper:https://arxiv.org/abs/2207.09332
人物交互检测
[1] Towards Hard-Positive Query Mining for DETR-based Human-Object Interaction Detection (面向基于 DETR 的人机交互检测的硬性查询挖掘)paper:https://arxiv.org/abs/2207.05293 code:https://github.com/muchhair/hqm
图像异常检测
[1] DICE: Leveraging Sparsification for Out-of-Distribution Detection (DICE:利用稀疏化进行分布外检测)paper:https://arxiv.org/abs/2111.09805code:https://github.com/deeplearning-wisc/dice
分割
实例分割
[1] Box-supervised Instance Segmentation with Level Set Evolution (具有水平集进化的框监督实例分割)paper:https://arxiv.org/abs/2207.09055
[2] OSFormer: One-Stage Camouflaged Instance Segmentation with Transformers (OSFormer:使用 Transformers 进行单阶段伪装实例分割)paper:https://arxiv.org/abs/2207.02255 code:https://github.com/pjlallen/osformer
语义分割
[1] 2DPASS: 2D Priors Assisted Semantic Segmentation on LiDAR Point Clouds (2DPASS:激光雷达点云上的二维先验辅助语义分割)paper:https://arxiv.org/abs/2207.04397 code:https://github.com/yanx27/2dpass
视频目标分割
[1] Learning Quality-aware Dynamic Memory for Video Object Segmentation (视频对象分割的学习质量感知动态内存)paper:https://arxiv.org/abs/2207.07922code:https://github.com/workforai/qdmn
图像处理
超分辨率
[1] Dynamic Dual Trainable Bounds for Ultra-low Precision Super-Resolution Networks (超低精度超分辨率网络的动态双可训练边界)paper:https://arxiv.org/abs/2203.03844 code:https://github.com/zysxmu/ddtb
图像去噪
[1] Deep Semantic Statistics Matching (D2SM) Denoising Network (深度语义统计匹配(D2SM)去噪网络)paper:https://arxiv.org/abs/2207.09302
图像复原/图像增强/图像重建
[1] Semantic-Sparse Colorization Network for Deep Exemplar-based Colorization (用于基于深度示例的着色的语义稀疏着色网络)paper:https://arxiv.org/abs/2112.01335
[2] Geometry-aware Single-image Full-body Human Relighting (几何感知单图像全身人体重新照明)paper:https://arxiv.org/abs/2207.04750
[3] Multi-Modal Masked Pre-Training for Monocular Panoramic Depth Completion (单目全景深度补全的多模态蒙面预训练)paper:https://arxiv.org/abs/2203.09855
[4] PanoFormer: Panorama Transformer for Indoor 360 Depth Estimation (PanoFormer:用于室内 360 深度估计的全景变压器)paper:https://arxiv.org/abs/2203.09283
[5] SESS: Saliency Enhancing with Scaling and Sliding (SESS:通过缩放和滑动增强显着性)paper:https://arxiv.org/abs/2207.01769
[6] RigNet: Repetitive Image Guided Network for Depth Completion (RigNet:用于深度补全的重复图像引导网络)paper:https://arxiv.org/abs/2107.13802
图像外推(Image Outpainting)
[1] Outpainting by Queries (通过查询进行外包)paper:https://arxiv.org/abs/2207.05312 code:https://github.com/kaiseem/queryotr
风格迁移(Style Transfer)
[1] CCPL: Contrastive Coherence Preserving Loss for Versatile Style Transfer (CCPL:通用风格迁移的对比相干性保留损失)paper:https://arxiv.org/abs/2207.04808 code:https://github.com/JarrentWu1031/CCPL
视频处理(Video Processing)
[1] Improving the Perceptual Quality of 2D Animation Interpolation (提高二维动画插值的感知质量)paper:https://arxiv.org/abs/2111.12792code:https://github.com/shuhongchen/eisai-anime-interpolator
[2] Real-Time Intermediate Flow Estimation for Video Frame Interpolation (视频帧插值的实时中间流估计)paper:https://arxiv.org/abs/2011.06294 code:https://github.com/MegEngine/arXiv2020-RIFE
图像、视频检索与理解
动作识别
[1] ReAct: Temporal Action Detection with Relational Queries (ReAct:使用关系查询的时间动作检测)paper:https://arxiv.org/abs/2207.07097code:https://github.com/sssste/react
[2] Hunting Group Clues with Transformers for Social Group Activity Recognition (用Transformers寻找群体线索用于社会群体活动识别)paper:https://arxiv.org/abs/2207.05254
视频理解
[1] GraphVid: It Only Takes a Few Nodes to Understand a Video (GraphVid:只需几个节点即可理解视频)paper:https://arxiv.org/abs/2207.01375
[2] Deep Hash Distillation for Image Retrieval (用于图像检索的深度哈希蒸馏)paper:https://arxiv.org/abs/2112.08816code:https://github.com/youngkyunjang/deep-hash-distillation
视频检索(Video Retrieval)
[1] TS2-Net: Token Shift and Selection Transformer for Text-Video Retrieval (TS2-Net:用于文本视频检索的令牌移位和选择转换器)paper:https://arxiv.org/abs/2207.07852code:https://github.com/yuqi657/ts2_net
[2] Lightweight Attentional Feature Fusion: A New Baseline for Text-to-Video Retrieval (轻量级注意力特征融合:文本到视频检索的新基线)paper:https://arxiv.org/abs/2112.01832
估计
位姿估计
[1] Category-Level 6D Object Pose and Size Estimation using Self-Supervised Deep Prior Deformation Networks (使用自监督深度先验变形网络的类别级 6D 对象姿势和大小估计)paper:https://arxiv.org/abs/2207.05444 code:https://github.com/jiehonglin/self-dpdn
深度估计
[1] Physical Attack on Monocular Depth Estimation with Optimal Adversarial Patches (使用最优对抗补丁对单目深度估计进行物理攻击)paper:https://arxiv.org/abs/2207.04718
目标跟踪
[1] Towards Grand Unification of Object Tracking (迈向目标跟踪的大统一)paper:https://arxiv.org/abs/2207.07078code:https://github.com/masterbin-iiau/unicorn
文本检测与识别
[1] Dynamic Low-Resolution Distillation for Cost-Efficient End-to-End Text Spotting (用于经济高效的端到端文本识别的动态低分辨率蒸馏)paper:https://arxiv.org/abs/2207.06694code:https://github.com/hikopensource/davar-lab-ocr
GAN/生成式/对抗式
[1] Eliminating Gradient Conflict in Reference-based Line-Art Colorization (消除基于参考的艺术线条着色中的梯度冲突)paper:https://arxiv.org/abs/2207.06095code:https://github.com/kunkun0w0/sga
[2] WaveGAN: Frequency-aware GAN for High-Fidelity Few-shot Image Generation (WaveGAN:用于高保真少镜头图像生成的频率感知 GAN)paper:https://arxiv.org/abs/2207.07288code:https://github.com/kobeshegu/eccv2022_wavegan
[3] FakeCLR: Exploring Contrastive Learning for Solving Latent Discontinuity in Data-Efficient GANs (FakeCLR:探索对比学习以解决数据高效 GAN 中的潜在不连续性)paper:https://arxiv.org/abs/2207.08630code:https://github.com/iceli1007/fakeclr
[4] UniCR: Universally Approximated Certified Robustness via Randomized Smoothing (UniCR:通过随机平滑获得普遍近似的认证鲁棒性)paper:https://arxiv.org/abs/2207.02152
神经网络结构设计
神经网络架构搜索(NAS)
[1] ScaleNet: Searching for the Model to Scale (ScaleNet:搜索要扩展的模型)paper:https://arxiv.org/abs/2207.07267code:https://github.com/luminolx/scalenet
[2] Ensemble Knowledge Guided Sub-network Search and Fine-tuning for Filter Pruning (集成知识引导的子网络搜索和过滤器修剪微调)paper:https://arxiv.org/abs/2203.02651 code:https://github.com/sseung0703/ekg
[3] EAGAN: Efficient Two-stage Evolutionary Architecture Search for GANs (EAGAN:GAN 的高效两阶段进化架构搜索)paper:https://arxiv.org/abs/2111.15097 code:https://github.com/marsggbo/EAGAN
数据处理
归一化
[1] Fine-grained Data Distribution Alignment for Post-Training Quantization (训练后量化的细粒度数据分布对齐)paper:https://arxiv.org/abs/2109.04186 code:https://github.com/zysxmu/fdda
模型训练/泛化
噪声标签
[1] Learning with Noisy Labels by Efficient Transition Matrix Estimation to Combat Label Miscorrection (通过有效的转移矩阵估计学习噪声标签以对抗标签错误校正)paper:https://arxiv.org/abs/2111.14932
模型压缩
知识蒸馏
[1] Knowledge Condensation Distillation (知识浓缩蒸馏)paper:https://arxiv.org/abs/2207.05409 code:https://github.com/dzy3/kcd)
模型评估
[1] Hierarchical Latent Structure for Multi-Modal Vehicle Trajectory Forecasting (多模式车辆轨迹预测的分层潜在结构)paper:https://arxiv.org/abs/2207.04624 code:https://github.com/d1024choi/hlstrajforecast
半监督学习/无监督学习/自监督学习
[1] FedX: Unsupervised Federated Learning with Cross Knowledge Distillation (FedX:具有交叉知识蒸馏的无监督联合学习)paper:https://arxiv.org/abs/2207.09158
[2] Synergistic Self-supervised and Quantization Learning (协同自监督和量化学习)paper:https://arxiv.org/abs/2207.05432 code:https://github.com/megvii-research/ssql-eccv2022)
[3] Contrastive Deep Supervision (对比深度监督)paper:https://arxiv.org/abs/2207.05306 code:https://github.com/archiplab-linfengzhang/contrastive-deep-supervision
[4] Dense Teacher: Dense Pseudo-Labels for Semi-supervised Object Detection (稠密教师:用于半监督目标检测的稠密伪标签)paper:https://arxiv.org/abs/2207.02541
[5] Image Coding for Machines with Omnipotent Feature Learning (具有全能特征学习的机器的图像编码)paper:https://arxiv.org/abs/2207.01932
多模态学习/跨模态
视觉-语言
[1] Contrastive Vision-Language Pre-training with Limited Resources (资源有限的对比视觉语言预训练)paper:https://arxiv.org/abs/2112.09331code:https://github.com/zerovl/zerovl
跨模态
[1] Cross-modal Prototype Driven Network for Radiology Report Generation (用于放射学报告生成的跨模式原型驱动网络)paper:https://arxiv.org/abs/ code:https://github.com/markin-wang/xpronet
小样本学习
[1] Learning Instance and Task-Aware Dynamic Kernels for Few Shot Learning (用于少数镜头学习的学习实例和任务感知动态内核)paper:https://arxiv.org/abs/2112.03494
迁移学习/自适应
[1] Factorizing Knowledge in Neural Networks (在神经网络中分解知识)paper:https://arxiv.org/abs/2207.03337 code:https://github.com/adamdad/knowledgefactor
[2] CycDA: Unsupervised Cycle Domain Adaptation from Image to Video (CycDA:从图像到视频的无监督循环域自适应)paper:https://arxiv.org/abs/2203.16244
强化学习
[1] Target-absent Human Attention (目标缺失——人类注意力缺失)paper:https://arxiv.org/abs/2207.01166 code:https://github.com/neouyghur/sess
